AI Video Trends 2026: What Is Changing and How to Use It
Sound, longer takes, consistent characters, vertical formats and disclosure rules are reshaping AI video this year. Here is what each shift means and how to use it.
Written by Vincent Park
Published
The biggest AI video trends 2026 are native audio, longer single takes, reference-based character consistency, vertical-first output and clearer labelling of AI content. As of October 2026, you can already use most of them inside VIBE, and this guide explains what each trend means for your clips, with copy-ready prompts you can try right away.
In one sentence
AI video trends 2026 are the shifts in how AI video models and platforms work this year: sound generated together with the picture, clips that run for many seconds, reference inputs that keep a character consistent, 9:16-first formats and disclosure rules for AI-made content.
AI video trends 2026: what are the biggest changes?
Five changes stand out, and each one is visible in the model announcements of the past few months rather than in speculation. Models now generate sound with the picture, single clips are getting longer, reference inputs make characters repeatable, vertical video is a default rather than an afterthought, and platforms are tightening how AI content is labelled. If you want the fundamentals first, our guide to writing AI video prompts covers the sentence structure that every one of these trends builds on.
- Native audio: dialogue, sound effects and ambience arrive in the same render as the picture.
- Longer takes: clips that run from 8 seconds up to a claimed 30 seconds change how you plan a scene.
- Reference-based consistency: photos, and in some models video and audio, steer who and what appears on screen.
- Vertical-first output: 9:16 is a standard format that models compose for, not a crop made afterwards.
- Disclosure and labels: platforms increasingly ask you to say when realistic content is AI-made.
Is native audio now standard in AI video?
It is becoming standard at the top end of the market, but it is not universal. Google DeepMind states that Veo 3.1 can add sound effects, ambient noise and dialogue, generating all audio natively, and Alibaba's Wan 3.0 launch announcement says the model supports native audio and video generation.
Inside VIBE the picture is more specific. As of October 2026, Veo 3.1 Fast and Kling 3 Pro render sound together with the video, while the other models in VIBE, Wan 3.0 included, render video only. Our AI video with audio guide compares the two in detail. The practical rule is to describe the sound in the prompt itself, in the same way you describe the camera and the light, and to name who speaks and what they say.
 Veo 3.1 Fast
“A street musician plays violin on a rainy corner at dusk, a passer-by says "Beautiful tune" and drops a coin in the case, close-up of the bow, warm shop light, rain on the pavement, soft violin music and rain ambience, vertical 9:16”
How long can an AI video clip be in 2026?
Clip length varies a lot by model, which is why it is a trend worth planning around. Google describes Veo clips as 8 seconds that can be extended with scene extension, Kling 3 Pro in VIBE reaches 15 seconds, and Alibaba states that Wan 3.0 can produce up to 30 seconds of video at up to 1080p. The table below puts the three side by side.
| Model | Maker | Clip length | Sound in VIBE |
|---|---|---|---|
| Veo 3.1 Fast | Google DeepMind | 8 seconds | Yes (native) |
| Kling 3 Pro | Kuaishou | Up to 15 seconds | Yes (native) |
| Wan 3.0 | Alibaba | Up to 30 seconds, per Alibaba | Video only |
A longer take is not automatically a better one. The more seconds a model has to fill, the more it can drift, so write one continuous action per clip and let the camera do the storytelling. If you want several beats, generate several clips and cut them together. The Wan model page shows how that model family handles motion, and the same one-action rule applies to every model in the table.
How do reference images keep characters consistent?
Reference inputs let you show the model what a character or object looks like instead of describing it from scratch. DeepMind says Veo 3.1 accepts reference images for characters, styles and objects, and Alibaba says Wan 3.0 can combine up to 10 images, 5 videos and 5 audio clips as references. In VIBE, the most reliable version of this idea today is image-to-video: you start from one photo that fixes the face, outfit and setting, as our photo-to-video guide explains.
- Pick one hero image with a clear, well-lit subject and use it as the starting frame for every clip.
- Reuse the exact same character description in every prompt, such as the clothing and hair, and change only the action.
- Keep one action per clip, so the model has nothing extra to invent about the character.
- Repeat the same style words, for example the lens, the light and the colour grade, in each prompt.
 Kling 3 Pro
“Using the uploaded photo as the first frame: the woman in the green raincoat turns toward the camera and smiles, then walks forward along the same market street, handheld camera at eye level, natural overcast light, same outfit and hairstyle throughout”
Why is vertical 9:16 the default format now?
Most AI video is watched on phones in TikTok, Instagram Reels and YouTube Shorts, so models and apps now treat 9:16 as a first-class format. DeepMind lists vertical 9:16 output as a Veo 3.1 capability, which means the model composes for a tall frame instead of cropping a wide one. Composing natively matters because a crop can cut off the subject or the action you planned.
- Put the subject in the middle third of the frame, away from the edges where app buttons and captions sit.
- Prefer one clear subject and a simple background, because small details disappear on a phone screen.
- Describe vertical movement, such as a tilt up or a subject walking toward the camera, to use the height of the frame.
- Choose 9:16 before you generate rather than cropping afterwards.
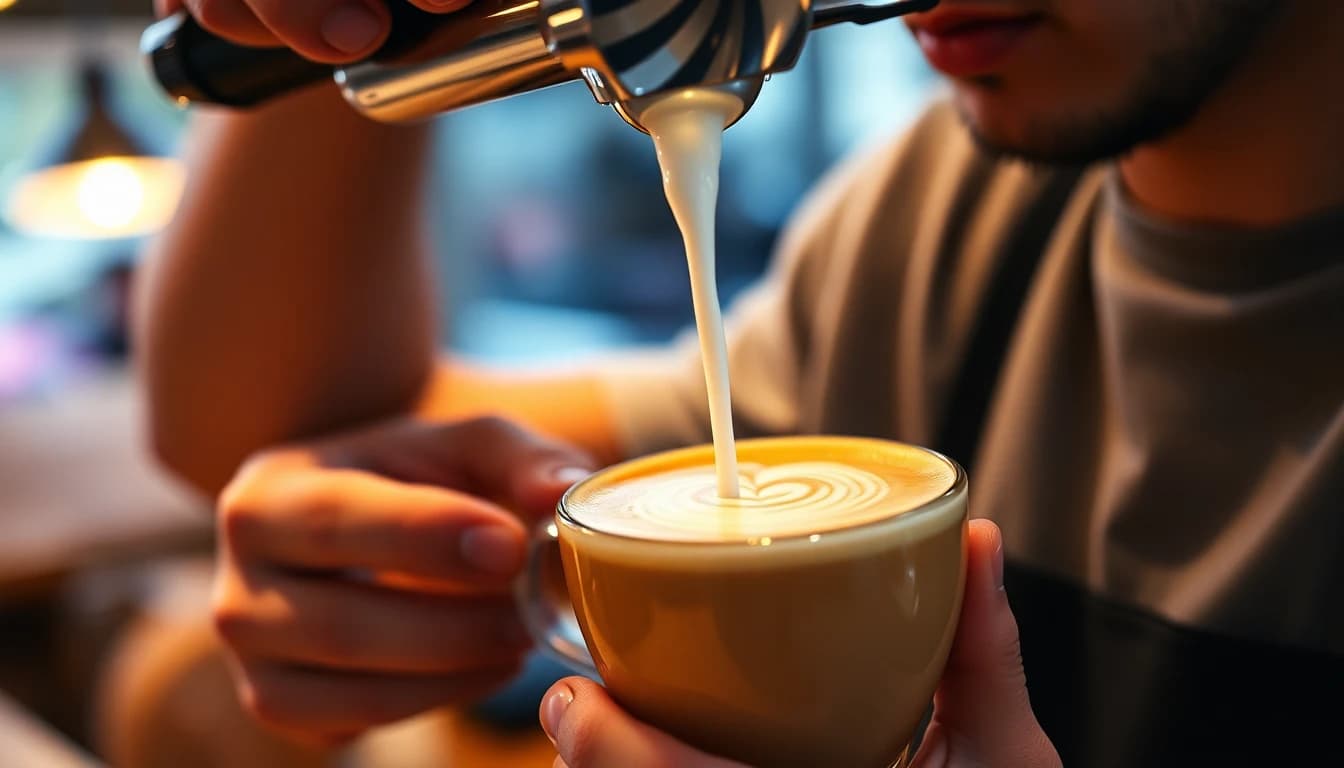
 Seedance Pro Fast
“Close-up of a barista pouring steamed milk into a latte, latte art forming, slow tilt up from the cup to a smiling face, warm cafe light, shallow depth of field, vertical 9:16”
What happened to Sora, and why does it matter?
OpenAI has discontinued Sora for general use, as its help centre explains, and our Sora 2 explainer covers the timeline and the alternatives. The lesson for creators is that no single model is permanent. Keep your prompts portable, save your best ones, and use an app that offers several models, so that a model changing or closing never stops your workflow. VIBE offers several models, including free ones, in a single app.
Do you have to label AI video in 2026?
On YouTube, yes, when the content is realistic. YouTube's policy asks creators to disclose meaningfully altered or synthetic content that looks realistic, with labels shown in the player for photorealistic content and in the description for animated or clearly non-realistic content. YouTube says disclosure does not limit reach or monetisation, but creators who repeatedly skip it can face labels added by YouTube, removal or suspension from the Partner Program. Rules differ by platform and change often, so check each platform's current help page before you post.
- Disclose realistic AI scenes that could be mistaken for real events or real people.
- Never use AI to make a real person appear to say or do something they did not.
- Use the AI setting at upload instead of hoping viewers will guess.
How can you use these trends in VIBE today?
- Open VIBE on iOS, Android or the web and start with a free model such as Seedance Pro Fast; no login is needed to try it.
- Write one action per clip and set the format to 9:16 for short-form platforms.
- Switch to Veo 3.1 Fast or Kling 3 Pro when you want dialogue and sound, or to Wan 3.0 when you want a longer take.
- Label realistic clips when you upload, and keep your best prompts for reuse.
Browse the full list of models, and which ones are free, in the VIBE models section, then try the prompt below to test a longer take.
 Wan 3.0
“One continuous shot following a hiker along a ridge trail at sunrise, the camera drifts slowly beside them as mist lifts from the valley, steady pace, soft golden light, natural motion, no cuts”
Frequently asked questions
What are the main AI video trends in 2026?
The main AI video trends 2026 are native audio, longer single clips, reference-based consistency, vertical 9:16 output and clearer disclosure of AI content. As of October 2026, models such as Veo 3.1, Kling 3 Pro and Wan 3.0 show several of these at once.
Which AI video models generate sound automatically?
In VIBE, Veo 3.1 Fast from Google DeepMind and Kling 3 Pro from Kuaishou generate sound together with the video. The other models in VIBE, including the free ones, currently produce picture only, so you add music or a voiceover afterwards.
How long can an AI video be in 2026?
It depends on the model. Veo 3.1 Fast makes 8-second clips, Kling 3 Pro goes up to 15 seconds, and Alibaba says Wan 3.0 can generate up to 30 seconds. Longer clips work best when planned as one continuous action.
Is there a free way to try these AI video trends?
Yes. VIBE has free models such as Seedance Pro Fast, LTX Video, Luma Dream Machine, Wan 2.6 and PixVerse, and you can try them without logging in. Premium models such as Veo 3.1 Fast, Kling 3 Pro and Wan 3.0 add sound or longer clips.
Do I need to label AI-generated videos?
On YouTube, you should disclose realistic content that is meaningfully altered or synthetic, using the AI setting in YouTube Studio. Other platforms have their own rules, so check each one before you post.
- #aivideotrends2026
- #aivideotrends
- #nativeaudioaivideo
- #verticalaivideo
- #aivideogenerator
Start Creating AI Videos Today
Download VIBE for free on iOS and Android. No login required. Access 10+ AI video models and generate videos from text prompts or images.
Keep reading
All articles Trends & tutorials
AI Video Generator for TikTok: Formats, Lengths and Prompts That Work
What a TikTok-ready AI clip looks like in 2026: vertical framing, the right length, sound that fits, honest labelling and five prompts you can paste into VIBE today.
Vincent Park9 min read Trends & tutorials
AI Video Generator With Audio: The Models That Add Sound Automatically
Two models inside VIBE generate audio the instant you hit render. Here's which ones, how they compare, and how to prompt for dialogue, sound effects and ambience that actually match the picture.
Vincent Park9 min read